References
Our testing protocol
100 queries, 4 platforms, 400 tests, and a scoring scale of 0 to 3 points.
The short answer
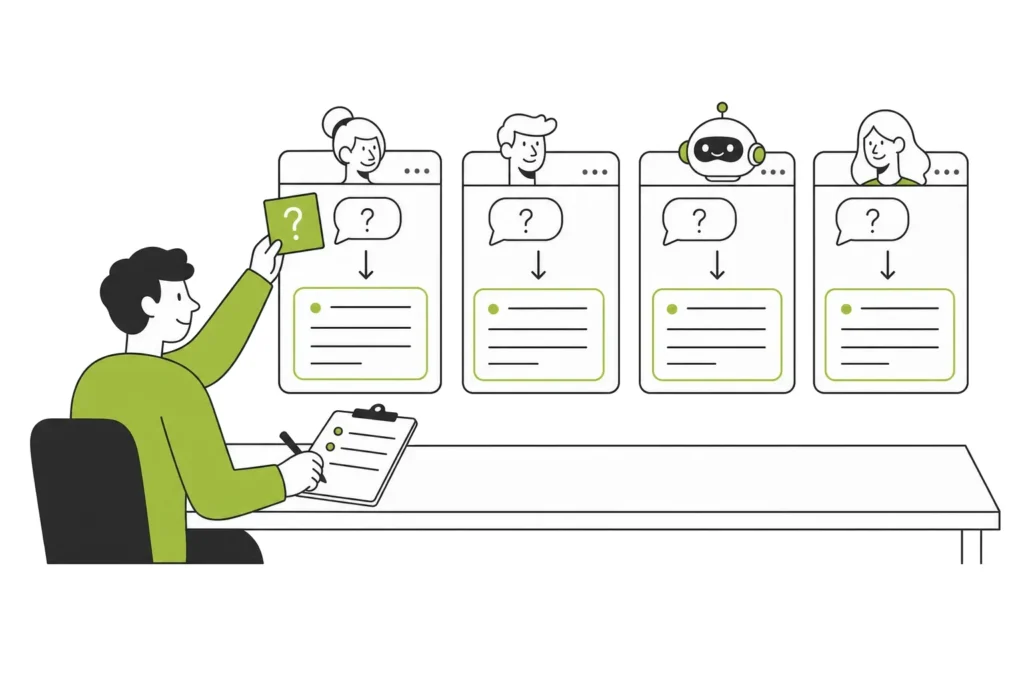
Our testing protocol measures your brand's visibility in the answers given by ChatGPT, Claude, Perplexity and Gemini. We put 100 strategic queries to each of the four platforms, 400 tests in all, and every answer is worth 0 to 3 points depending on your position. Your visibility is the score obtained divided by 1,200, multiplied by 100.
400 tests
100 strategic queries put to 4 platforms: ChatGPT, Claude, Perplexity and Gemini
1,200 points
Maximum possible: 100 queries × 4 platforms × 3 points at most
41%
Longer visits from generative AI traffic than from non-AI traffic, with a 23% lower bounce rate (Adobe Digital Insights, Adobe Analytics, July 2024 to February 2025, published May 23, 2025)
Real tests, not simulated
This is our first commitment: the tests are real, not simulated. We put the queries to the platforms themselves and score what they answer. These tests are the fourth phase of our GEO method and take 8 to 12 hours. The protocol is constant, so the results can be verified and compared. It is what measures the thing our AI search engine optimization engagements set out to improve: your brand's presence in the answers.
A hundred queries, four families
The 100 strategic queries break down as follows: 60 semantic, 20 competitive, 15 semi-branded and 5 branded. In other words, only 5 queries out of 100 are branded, and more than half are semantic. The same 100 queries are put to all four platforms, which makes it possible to compare their answers with one another, query by query. A shorter pre-quote audit applies the same scale and the same families to a reduced corpus: it gives an order of magnitude, not a reference measurement, and the report always states how many queries it covers.

Four platforms, one scoring scale
We test ChatGPT, Claude, Perplexity and Gemini, the four engines that matter. Each query is put to all four, and every answer is scored on the same scale. Your brand is not mentioned: 0 points. It is mentioned in position 3 or beyond: 1 point. In position 2: 2 points. In position 1: 3 points. The scale therefore rewards the place you hold in the answer, not just the fact of being in it.
From score to percentage
The calculation fits on one line. 100 queries, multiplied by 4 platforms, multiplied by a maximum of 3 points, give 1,200 possible points. Your visibility as a percentage is the score obtained, divided by 1,200, multiplied by 100. You receive the measurements by query and by platform, with full access to the data and the results. That is our second commitment: complete transparency.

Our approach in 4 steps
- 01
Queries
100 strategic queries: 60 semantic, 20 competitive, 15 semi-branded and 5 branded.
- 02
Tests
Each query is put to ChatGPT, Claude, Perplexity and Gemini, 400 real tests in all.
- 03
Scoring
Each answer is worth 0 points if your brand is not mentioned, 1 point in position 3 or beyond, 2 points in position 2, 3 points in position 1.
- 04
Calculation
Visibility % = score obtained ÷ 1,200 × 100. You receive the measurements by query and by platform, which feed the rest of our method.
Frequently asked questions
Why 400 tests?
Because we put 100 strategic queries to 4 platforms: ChatGPT, Claude, Perplexity and Gemini. Each combination of one query and one platform is a test, scored from 0 to 3 points. That makes 400 tests and 1,200 possible points, which gives a measurement by query and by platform rather than an overall impression.
How is an answer scored?
By the position of your brand in the answer. If it is not mentioned, the answer is worth 0 points. If it appears in position 3 or beyond, 1 point. In position 2, 2 points. In position 1, 3 points. The same scale applies to all four platforms and all 100 queries, which makes the results comparable with one another.
How is our visibility percentage calculated?
Visibility % = score obtained ÷ 1,200 × 100. The 1,200 points are the maximum possible: 100 queries, 4 platforms, 3 points per answer. A brand cited in first position in every answer would therefore score 100%. The percentage is read alongside the breakdown by query and by platform, which you receive together with full access to the data.
How are the 100 queries split?
Into four families: 60 semantic queries, 20 competitive, 15 semi-branded and 5 branded. The same 100 queries are put to ChatGPT, Claude, Perplexity and Gemini, following a constant protocol: that is what makes the results verifiable and comparable.
Why measure visibility in AI answers?
Because this traffic is worth winning. Adobe Digital Insights measured, from July 2024 to February 2025, generative AI referral traffic multiplied by 12 to retail sites. Those visits bounce 23% less, view 12% more pages and last 41% longer than non-AI traffic (Adobe Analytics, published May 23, 2025).
Can we see a test live?
Yes, that is how we start. The free AI visibility audit takes 30 minutes: we test your brand live on the four platforms, in front of you. The full protocol, with its 400 tests, comes afterwards, as part of the complete analysis described in our GEO method.
Do you run shorter audits?
Yes, for a pre-quote. The scale, the four query families and the four platforms are the same, on a reduced corpus. It gives an order of magnitude, useful for deciding whether there is an engagement to run, but it is not the reference measurement: only the 100-query version serves as a starting point for tracking over time. The report always states how many queries it covers.
Let's measure your AI visibility
Thirty minutes to find your next step. You describe your situation, we tell you where to start.
- An answer by the next business day
- A person from our team, not a bot
- A first concrete recommendation
Your request has arrived.
A senior team member will get back to you by the next business day. A confirmation email is on its way.